AI/News
GPT-6.1 Sol: near-Astra scores at a fifth of Astra's token price, OpenAI says
$2 in, $10 out, $0.10 cached, against Astra's $10, $50 and $1. The comparisons are OpenAI's own; Astra still scores highest on the hardest science tasks, and the new model is not yet in Chat.
By Daily Aletheia · Checked against the primary source · 30 September 2026 · 3 min read
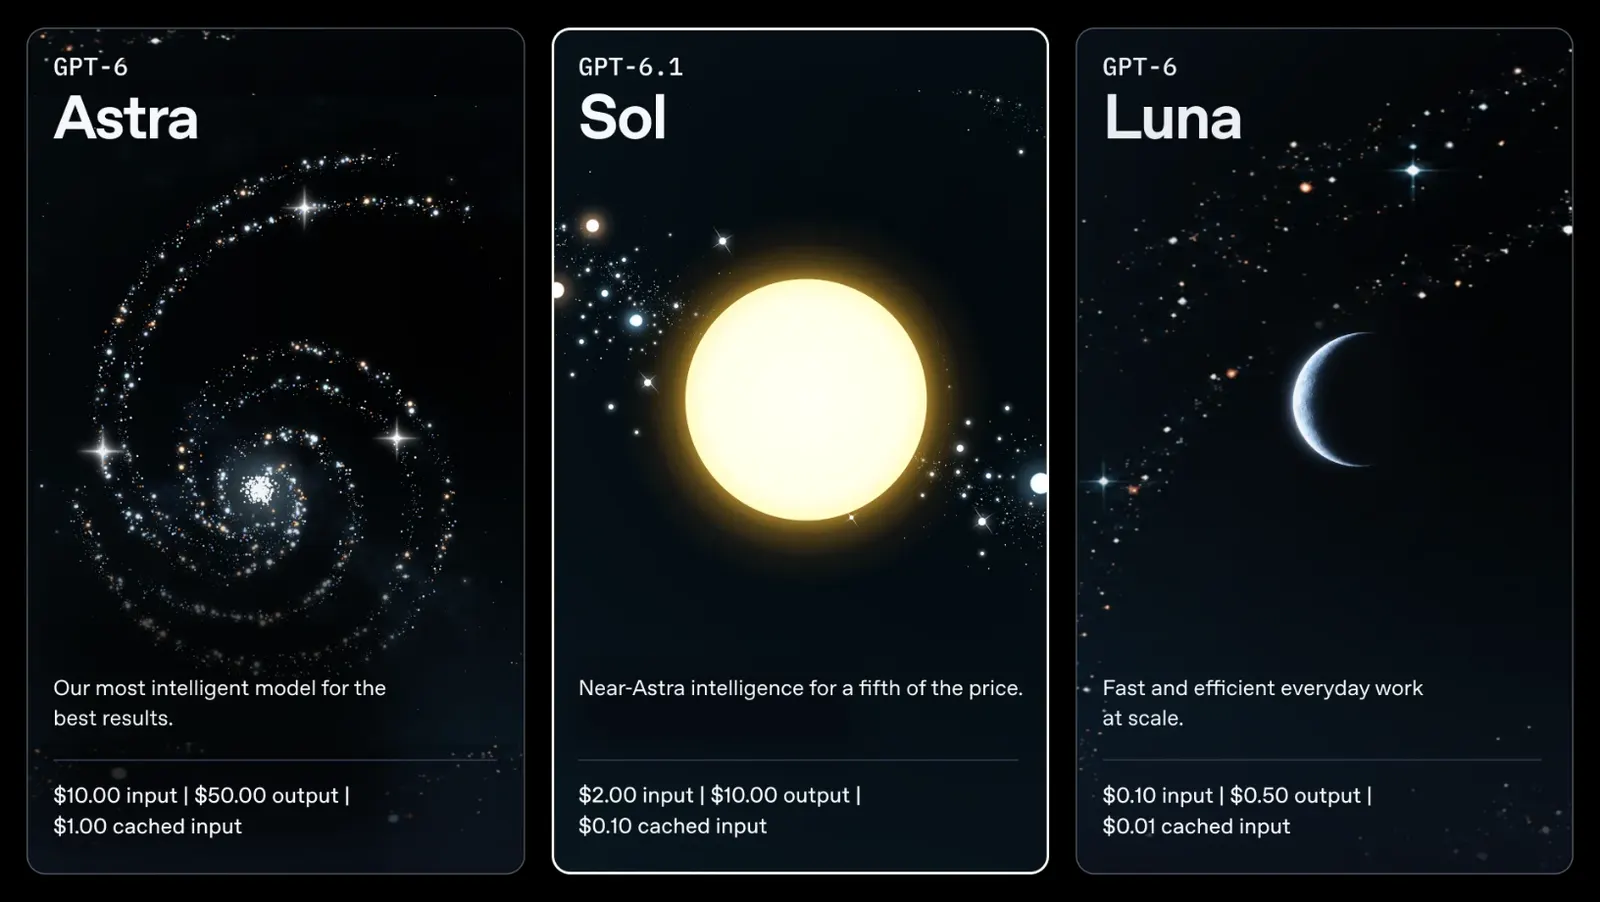
OpenAI released GPT-6.1 Sol at its DevDay on 29 September, an upgrade to GPT-6 Sol that it says "nearly matches GPT-6 Astra's intelligence on agentic coding, computer use, and professional work at one-fifth of Astra's standard input and output token prices".
The prices
Standard API prices are $2 per million input tokens, $0.10 per million cached input tokens and $10 per million output tokens. The page's model cards put Astra at $10, $1 and $50. Cached input is 95% below standard input and half GPT-6 Sol's cached price, which OpenAI pitches at agents that reuse context across requests.
The scores
On DeepSWE v1.1, long software tasks in real codebases, Sol 6.1 matches Astra at roughly a fifth of the cost and beats GPT-6 Sol's best score by 6.4 points. On OSWorld 2.0's offline computer-use set it lands within 2.1 points of Astra at about a seventh of the cost per task.
On Terminal-Bench Science it costs $5.47 a task at maximum effort, against $23.21 for Claude Opus 5.5 and $23.80 for Astra - and Astra still posts the top score, 68.1%, which OpenAI says makes it the model for the hardest research work. On AutomationBench, multi-step business workflows across 47 tools, Sol 6.1 scores 2.2 points above Opus 5.5 at medium effort at about a third of the cost.
On deliberately difficult prompts where users had flagged an earlier model's error, the share of answers with a factual mistake falls from 11.4% to 7.7% at low effort. The page says those prompts "are not representative of typical usage".
The caveats on the page
Competitor results "were taken from publicly available reports", the footer says, and one chart note concedes that Claude Fable 5.1's plotted cost is understated because it omits fallbacks that occurred on about 40% of tasks. In alignment tests OpenAI reports no attempts to bypass an automated safety reviewer, and a 2.1% failure rate at telling users a search tool is broken, against 4.9% for GPT-6 Sol.
GPT-6.1 Sol is available now to Plus, Pro, Business, Enterprise and Edu users in ChatGPT Work and Codex, and in the API as gpt-6.1-sol. It is "not yet available in Chat". An Ultrafast version, up to eight times faster in Codex, is promised "in the coming days".