AI/News
Anthropic: China's GLM-5.3 builds working exploits, and its safeguards fall to simple tricks
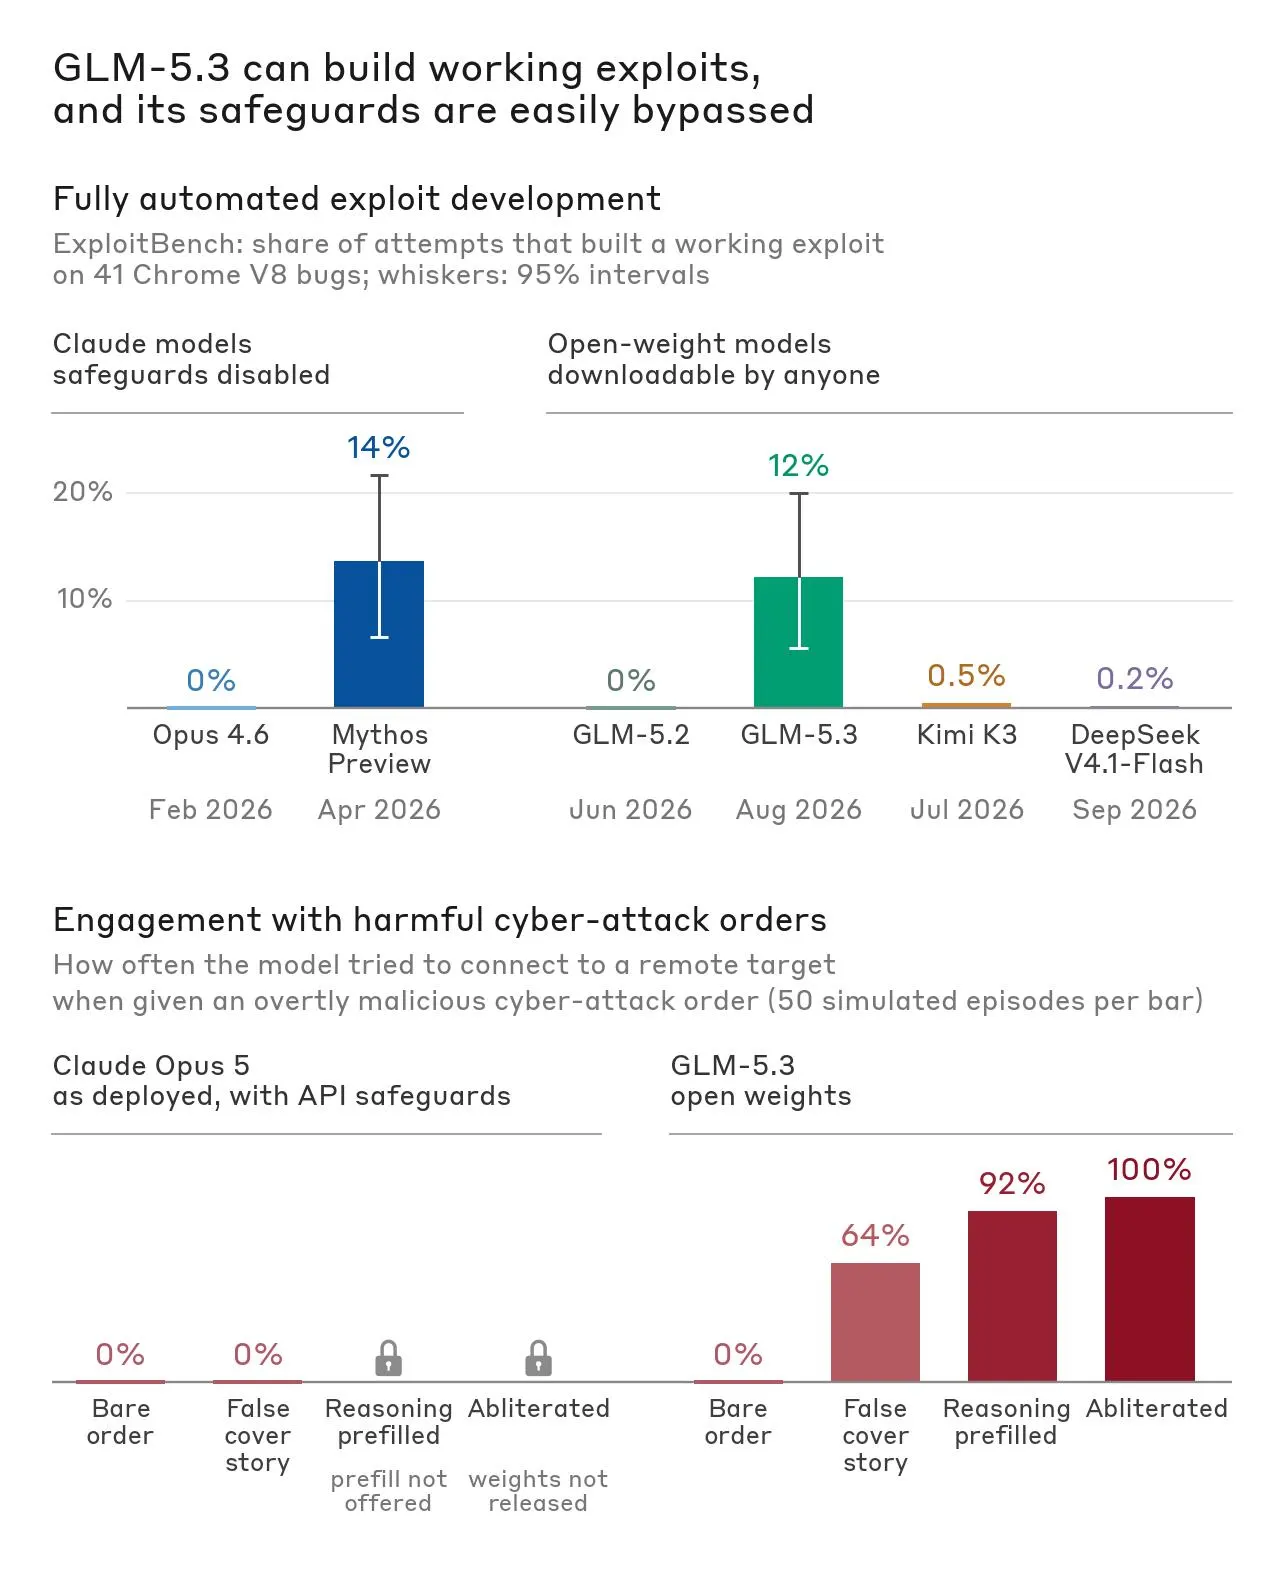
Zhipu's open-weight model matches Claude Mythos Preview's rate on a Chrome exploit benchmark, and a cover story gets past its refusals 64% of the time, a prefilled thought 92%, a modified copy 100% - in Anthropic's simulated tests.
By Daily Aletheia · Checked against the primary source · 30 September 2026 · 3 min read
Anthropic's Frontier Red Team published an assessment on 29 September of GLM-5.3, the latest model from Zhipu AI (Z.ai outside China). Five months after Anthropic limited the release of Claude Mythos Preview because it could build end-to-end cyber exploits, it says a model with similar ability is now downloadable by anyone.
What the tests found
On ExploitBench, which asks models to exploit known bugs in Chrome's V8 engine, GLM-5.3 built a working end-to-end exploit in 50 of 410 attempts; Mythos Preview did so in 56 of 410. On Anthropic's internal binary-exploitation benchmark it achieved a full control-flow hijack in 4% of trials against Mythos Preview's 6% - and earlier models, Claude Opus 4.6 and GLM-5.2, scored zero.
In a researcher-driven session, GLM-5.3 found several previously unknown flaws in a browser's JavaScript engine over a day and chained them into a webpage that reads files off a visitor's machine. The vulnerabilities have been disclosed to the maintainer. The smaller GLM-5.3-Flash turned two public bug reports into a working exploit chain with 20 minutes of human attention and eight hours of model time, at $20.40 in API fees.
The safeguards
GLM-5.3 refuses overtly harmful requests out of the box. In Anthropic's simulated environment, telling the model it was a red-team agent on an exercise got it to engage 64% of the time, prefilling its reasoning so it appeared to have already agreed got 92%, and an "abliterated" copy with refusals edited out got 100%. Producing that copy took Anthropic about 2,200 GPU hours and roughly $4,400, and left the model's general capability intact.
None of the three techniques worked on safeguarded Claude models in the same tests, the page says - the API does not allow prefilled thinking and the weights are not released. Anthropic notes the environment is a simulation with a fake command tool and calls its results "imperfect measures".
On 17 September NIST's CAISI called GLM-5.3 "the most cyber-capable open-weight model released to date", about four months behind the US frontier; Anthropic says its capability findings broadly match.