AI/News
Anthropic says Claude now leads a quarter of its own AI research - on a scale Claude scored
Three measurements published 17 September put Claude at the "leads" rung for 26% of Anthropic's R&D work. The headline that followed dropped the supervision, the platform caveat and who did the scoring.
By Daily Aletheia · Checked against the primary source · 22 September 2026 · 3 min read
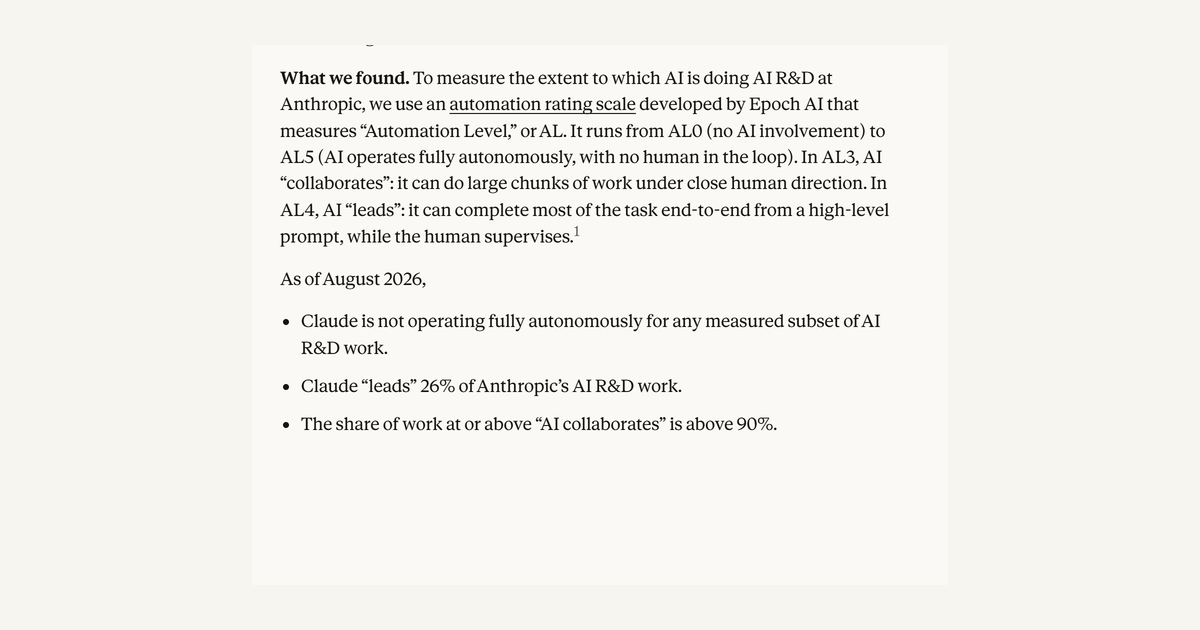
Anthropic published three measurements on 17 September under the title "Measurements for understanding the pace of AI development inside frontier labs." The coverage compressed them into four words: AI is now building AI.
What the page says
Claude leads 26% of Anthropic's AI research and development work, measured in August. "Leads" is a defined rung on an automation scale built by Epoch AI: the model completes most of a task end-to-end from a high-level prompt while a human supervises. Work sitting at or above the rung below it, "collaborates," is above 90%. Around 30,000 agents were doing research and engineering work at any one time in August - on the company's most-used internal platform, which the page says is the only platform these measurements cover. Anthropic states plainly that Claude is not operating fully autonomously for any measured subset of that work.
Every action those agents take passes an online monitor before it executes. Of more than a billion decisions analysed in August, 0.002% were blocked - about one in 47,000.
Who did the scoring
The index is not an audit. It was built by Claude: a Claude research agent worked out how each kind of work is done, and an independent Claude judge assigned the automation level. Anthropic names the weakness itself - the judge model "could make the same kinds of errors as the model it is checking." When the judge was checked against the staff who own the work, it matched them exactly 59% of the time; those humans matched each other 35% of the time. Anthropic says it plans to embed independent third-party evaluators with access comparable to its internal risk teams. That has not happened yet for these numbers.
Why it matters
The number is real and it is large. It is also a quarter, not the whole; led under supervision, not autonomous; on one platform, not the company; and scored by the model being measured. Read it as the first honest yardstick of how much of a frontier lab's own work a model now carries - and read the four-word version as what happens to a yardstick on its way through a headline.
The check
- What was said
- "AI is now building AI."
- What the source says
- Claude leads 26% of Anthropic's R&D work, supervised; above 90% at or above "collaborates"; ~30,000 agents on one internal platform; not fully autonomous on any measured subset; scored by a Claude judge that agreed with humans 59% of the time.
- The difference
- A quarter of the work, under supervision, on one platform, self-scored. The headline drops all four qualifiers.
Sources & further reading
This item appeared in the 22 September 2026 issue.